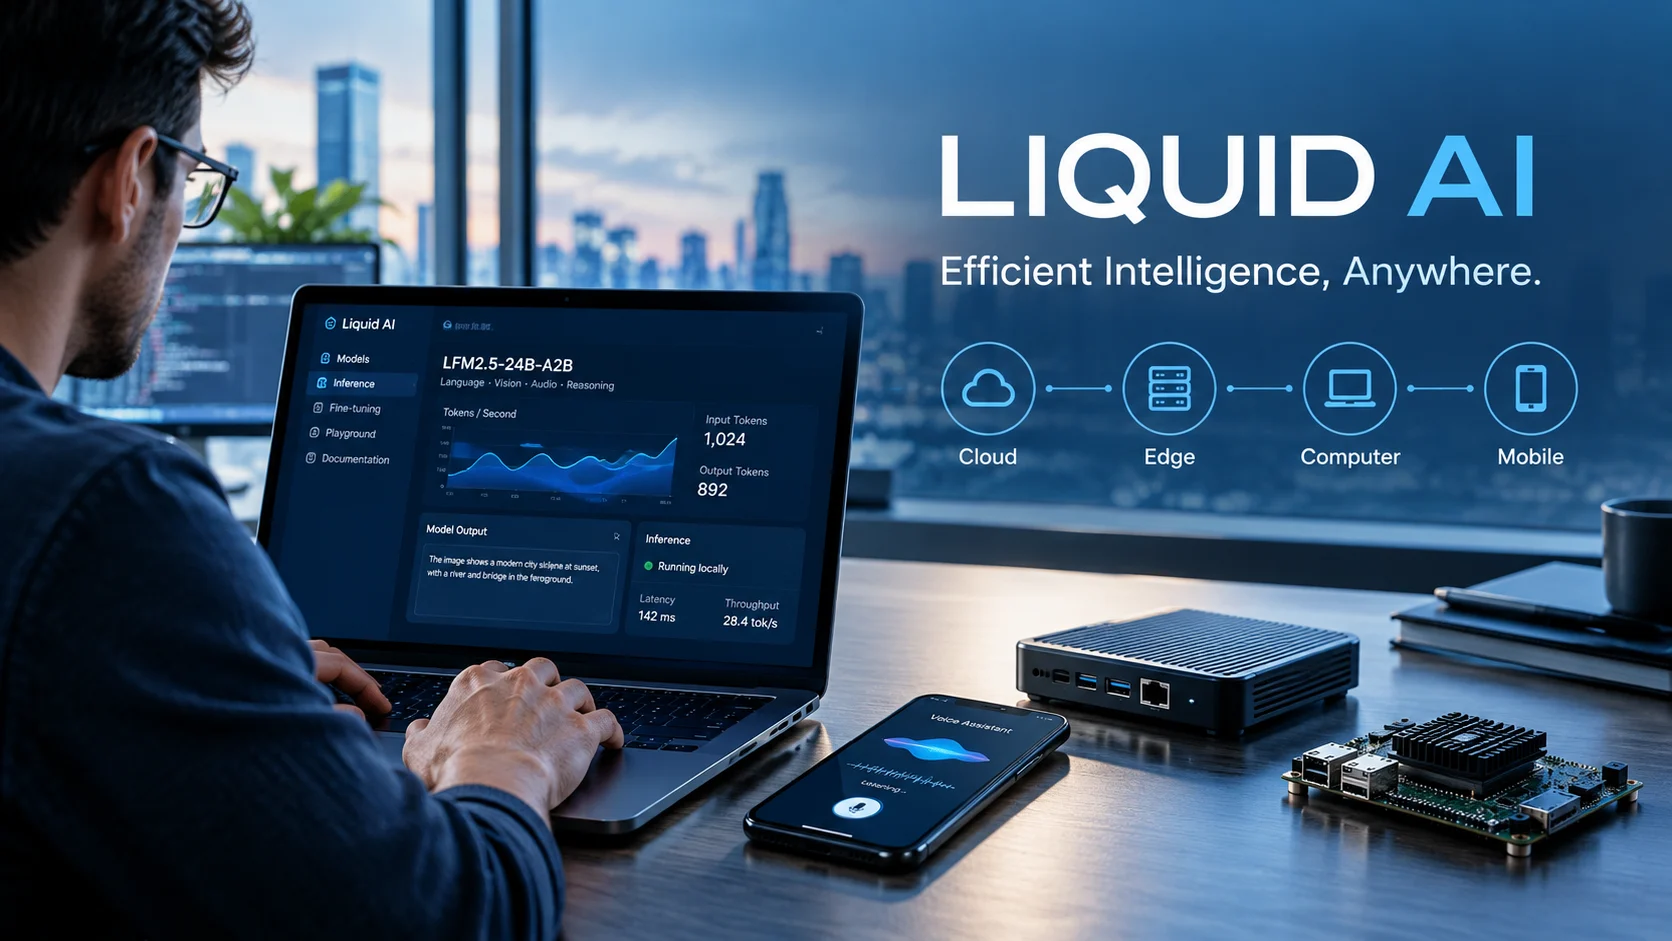
Liquid AI is an artificial intelligence company that develops Liquid Foundation Models (LFMs), designed to deliver efficient AI across phones, computers, embedded devices, and cloud environments. Its open-weight models support tasks involving text, vision, audio, and decision-making, giving developers options for local deployment, customization, and API-based applications.
Liquid AI at a Glance
- What it is: An AI company focused on efficient foundation models and practical deployment.
- Core technology: Liquid Foundation Models, including the LFM2.5 family and specialized decision models.
- Main advantage: Options for running AI on local hardware rather than relying entirely on cloud inference.
- Available formats: Depending on the model, developers can use GGUF, MLX, ONNX, Transformers, and compatible inference engines.
- Pricing: API usage is billed by tokens for supported models; open-weight licensing follows separate terms.
- Ideal users: AI developers, researchers, product teams, and businesses building applications with hardware or latency constraints.
What Is Liquid AI?
Liquid AI is an AI company founded in 2023 that develops foundation models designed for real-world computing environments. Rather than focusing exclusively on large models running in data centers, the company emphasizes efficient architectures that can operate across cloud infrastructure and resource-constrained devices.
Its primary model family is called Liquid Foundation Models (LFMs). These models cover several categories, including language, vision-language, audio, compact task-specific models, and decision-making.
This approach matters because many AI applications do not need a massive cloud model for every interaction. A smartphone assistant might need to respond quickly, while a connected device may need to classify information without sending every request to a remote server.
Liquid AI aims to address these requirements through model design, optimization, and flexible deployment options.
The company is not simply an AI chatbot. It provides models and infrastructure options that developers can use to build their own products, agents, and intelligent device experiences.
Liquid AI Models: Which Ones Are Available?
Liquid AI’s model lineup includes language models, vision-language models, audio models, compact task-specific models, and decision models. Each category serves different workloads, so choosing by model size alone can lead to poor results.
The company’s official model directory is the best starting point for checking current releases and supported formats.
These models handle text generation, instruction following, and related language tasks. The family includes small models for constrained hardware and larger options for more demanding workloads.
Use cases: Local assistants, structured extraction, text processing, and tool-using agents.
Vision-language models process visual information alongside text. Depending on the specific model, they can support image understanding, extraction, and visual analysis.
Use cases: Product inspection, image-based workflows, and applications that need to interpret visual inputs.
The audio family supports audio and text workflows, including applications involving spoken interaction.
Use cases: Voice assistants, conversational interfaces, and speech-enabled devices.
Liquid AI’s d1 family is designed to produce structured decisions and probabilities for defined outcomes rather than always generating a long natural-language answer. Liquid released open-weight d1 models in October 2026.
Use cases: Classification, filtering, routing, and certain visual inspection workflows.
What is LFM2.5-24B-A2B?
Released on October 13, 2026, LFM2.5-24B-A2B is a larger reasoning model in Liquid AI’s LFM2.5 family. The model has 24 billion total parameters, with approximately 2 billion active per token because it uses a sparse mixture-of-experts architecture.
In simple terms, the model contains specialized groups of parameters, but only selected groups handle each token. This can reduce computation compared with activating the entire model for every token, although memory requirements and actual performance still depend on the implementation.
Liquid AI reports a context window of 131,072 tokens for this model. That is a substantial increase over the 32,768-token context described for earlier LFM2 releases.
The larger model is particularly relevant to developers building agents that need reasoning and tool use. However, its published benchmark results are vendor-reported and should be validated against your own tasks and hardware.
How Does Liquid AI Work?
Liquid AI develops models using an architecture inspired by ideas from dynamical systems, rather than relying exclusively on conventional Transformer blocks.
Its LFM2 architecture combines gated short convolution blocks with grouped-query attention. These components help the models process information while balancing computational cost, memory use, and model quality.
You do not need to understand the underlying mathematics to use Liquid AI. The practical point is that the company is optimizing model architecture for environments where processing power, memory, battery life, or response time matters.
Local inference versus cloud inference
Liquid AI supports two broad deployment approaches.
| Factor | Local or edge inference | Cloud API inference |
|---|---|---|
| Processing | Runs on your device or infrastructure | Runs on a provider’s infrastructure |
| Connectivity | Can work offline after setup, depending on the application | Usually needs a network connection |
| Privacy | Can reduce external data transfers | Depends on provider policies and configuration |
| Cost | Hardware, power, and maintenance | Usage fees and infrastructure costs |
| Scaling | Limited by available local resources | Can scale with available service capacity |
| Maintenance | You manage runtime and model updates | Provider manages much of the serving infrastructure |
Local inference is not automatically private or inexpensive. Your application may still transmit telemetry, use external APIs, or store sensitive data. Likewise, cloud deployment may be the more economical option when requests are infrequent or local hardware is expensive.
Key Features of Liquid AI
1. Open-weight model access
Liquid AI makes many models available for download, allowing developers to run and adapt them rather than accessing them exclusively through a hosted chatbot.
Open weights provide more deployment flexibility, but they do not necessarily mean every aspect of training data, training code, or development infrastructure is open source.
2. Multiple deployment formats
Depending on the model, Liquid AI supports formats and runtimes such as GGUF, MLX, ONNX, llama.cpp, Transformers, vLLM, and SGLang. These options make it possible to target different operating systems, processors, and serving environments.
For example, MLX is relevant to Apple silicon, while ONNX can support cross-platform inference. GGUF is commonly used with local inference tools such as llama.cpp.
Check the individual model card before choosing a runtime. Format availability is not identical across the entire model family.
3. Fine-tuning and customization
Developers can adapt supported open-weight models to specialized tasks using fine-tuning and other model-customization techniques.
Fine-tuning changes model behavior through additional training. It differs from retrieval-augmented generation (RAG), which supplies relevant external information at inference time.
The right approach depends on whether you need a specialized response style, a defined output format, access to changing knowledge, or a combination of these capabilities.
4. Support for AI agents
An AI agent can use a model to select tools, interpret results, and complete a sequence of actions.
Liquid AI’s recent models emphasize tool calling and agent-oriented workloads. Still, the model is only one part of the system. Developers also need reliable tools, permission controls, error handling, and a way to review actions before they affect important data or systems.
Liquid AI Pricing: Is It Free?
Liquid AI offers three main routes: hosted API access, open-weight model licensing, and custom deployments. The cost depends on how you use the models and whether you run them yourself or pay for hosted inference.
Current API pricing
The company’s official pricing page currently lists these rates. Prices can change, so check the live page before budgeting.
| Model | Input price per 1 million tokens | Output price per 1 million tokens |
|---|---|---|
| d1 | $0.02 | $0.00 |
| LFM2.5-24B-A2B | $0.05 | $0.70 |
Liquid AI also advertises $2 in free API credit for each new organization. The pricing page states that prices are the same across supported access platforms, although billing is handled by the platform you use.
These rates are not a complete estimate of application costs. You may also pay for hosting, storage, retrieval, external tools, and additional infrastructure.
Open-weight model licensing
Liquid AI’s LFM Open License includes an important commercial-use condition:
- Companies with annual revenue below $10 million can use the covered open-weight models commercially under the free license.
- Companies exceeding that revenue threshold must obtain a commercial license for continued commercial use.
- Research, education, and qualifying nonprofit use receive specified exemptions.
- The license permits private fine-tunes without a copyleft requirement, subject to its terms.
Liquid AI+1
This is an important distinction: open weights do not mean unrestricted licensing. Businesses should review the full license, including its definitions, attribution requirements, and commercial-use provisions, before deploying a model.
See the official Liquid AI pricing page and LFM Open License for current terms.
Liquid AI vs. Other AI Model Providers
Liquid AI competes in the broader foundation-model ecosystem, but its emphasis on efficient deployment creates a different set of trade-offs from services focused primarily on large cloud models.
| Platform | Main focus | Potential strength | Main consideration |
|---|---|---|---|
| Liquid AI | Efficient models for edge, local, and cloud deployment | Open weights and multiple deployment options | Hardware and licensing requirements vary |
| Google Gemma | Open-weight general-purpose models | Model variety and ecosystem support | Capabilities and licenses differ by model |
| Microsoft Phi | Compact language and multimodal models | Small-model deployment and research options | Model-specific capabilities and terms |
| Alibaba Qwen | General-purpose and specialized models | Broad model selection and deployment options | Licensing, hardware needs, and quality vary |
| Mistral AI | Open and commercial AI models | Developer tools and multiple deployment approaches | Access terms differ across offerings |
These are broad ecosystem comparisons, not claims that one provider consistently outperforms another. Model families change frequently, and some offerings are proprietary while others publish downloadable weights.
For a fair evaluation, compare models at similar quantization levels and on the same hardware. Test the actual workload, including response quality, memory consumption, time to first token, total latency, and cost per completed task.
Useful places to inspect available models include the Hugging Face Hub, the official Liquid AI model directory, and the providers’ own documentation. Model directories help you discover options, but they do not independently validate performance claims.
Privacy and Security: Can Liquid AI Run Offline?
Yes, supported Liquid AI models can run locally when you download the appropriate weights and use a compatible runtime and device. The company’s documentation lists local deployment options for computers and edge hardware.
Running a model locally can reduce the need to send prompts and documents to a third-party inference API. This can help organizations that need greater control over sensitive data.
However, local inference does not automatically make an entire application secure. The application may still connect to external services, synchronize files, collect telemetry, or expose data through insecure storage.
Before deployment, consider these safeguards:
- Network access: Confirm whether the application makes any external requests.
- Data handling: Review where prompts, outputs, logs, and uploaded files are stored.
- Access controls: Protect model files and connected tools with appropriate permissions.
- Updates: Track model and runtime updates, including security fixes.
- API privacy: For hosted inference, read the provider’s retention and data-processing terms.
- Compliance: Assess the complete application against your organization’s legal and regulatory obligations.
Do not assume Liquid AI’s hosted API and locally deployed models have identical data-handling properties. Their architectures and operational arrangements differ. Likewise, a security certification or vendor statement should be evaluated within its stated scope rather than treated as a universal guarantee.
Limitations and Common Mistakes
Liquid AI offers useful deployment flexibility, but it is not automatically the right choice for every project.
Choosing a model by parameter count alone
A larger model is not always better for a particular task. A compact classifier may outperform a generative model on a narrow classification workflow, while a more capable reasoning model may be necessary for complex tool use.
Select based on measured task quality, not size alone.
Assuming local models require no infrastructure
A model that runs on a laptop still needs memory, processing capacity, storage, and a suitable runtime. Quantization can reduce resource requirements, but it may also affect output quality.
Test the exact model build and configuration on the target device.
Ignoring license restrictions
Liquid AI’s open-weight license includes a revenue threshold for commercial use. Companies should not assume they can use the models indefinitely for free simply because the weights are downloadable.
Treating benchmark results as universal
Benchmarks measure performance under particular conditions. Hardware, prompt length, quantization, concurrency, and software versions can change the results.
Build a representative test set and measure end-to-end performance before committing to a model.
Underestimating integration costs
The model itself may be inexpensive, but production deployment also involves monitoring, retries, evaluation, security, and maintenance. These costs can outweigh token charges for smaller workloads.
Who Should Use Liquid AI?
Liquid AI is worth evaluating if you are building products that need efficient inference, offline operation, or greater control over where AI processing takes place.
- Developers: Build local assistants, tool-calling agents, and applications that use open-weight models.
- Startups: Experiment with hosted APIs before deciding whether self-hosting is worthwhile.
- Enterprise teams: Explore local deployment, customization, and hardware-specific optimization.
- Researchers: Inspect model behavior, test fine-tuning approaches, and evaluate alternative architectures.
- Device manufacturers: Investigate AI features for phones, computers, vehicles, and embedded systems.
It may be less suitable if you need a ready-made consumer chatbot, have no capacity to manage local deployment, or require capabilities that a specific LFM model does not support.
For developers, the most practical starting point is the official Liquid AI documentation and model playground. Test a small model first, establish a quality baseline, and scale only when the results justify it.
Frequently Asked Questions About Liquid AI
1. Is Liquid AI free to use?
Liquid AI offers API access with usage-based pricing and open-weight models under its LFM Open License. Eligible companies below the $10 million annual revenue threshold can use covered models commercially under the free license. Larger businesses need a commercial license, subject to the license terms.
2. What is the difference between Liquid AI and ChatGPT?
Liquid AI primarily provides models and deployment options that developers can use to build applications. ChatGPT is a consumer-facing AI assistant. Liquid AI supports local model deployment for compatible models, while ChatGPT is accessed as a hosted product. They serve different purposes.
3. Can Liquid AI run locally without an internet connection?
Yes, compatible Liquid AI models can run locally using supported runtimes and downloaded model files. Once everything is installed, inference can work offline, provided the application does not depend on external APIs or online services. Hardware requirements depend on the chosen model and configuration.
4. Is Liquid AI open source?
Liquid AI provides open-weight models under its LFM Open License. Users can download, modify, and deploy covered models, subject to the license’s conditions. Open weights do not necessarily include all training data or training infrastructure, and the license’s commercial-use threshold matters for businesses.
5. Which Liquid AI model should developers choose?
Choose according to the workload. Compact LFM2.5 models suit constrained devices and targeted tasks, vision-language models support visual inputs, audio models address speech-related applications, and d1 models focus on structured decisions. Test the relevant model against your own quality, latency, memory, and cost requirements.
Conclusion
Liquid AI is developing a model ecosystem focused on efficient inference, flexible deployment, and AI that can operate beyond traditional cloud infrastructure. Its LFM2.5 family and d1 decision models give developers options for language tasks, multimodal applications, and structured decision-making.
The most important factors are model capability, hardware compatibility, deployment costs, and licensing. Developers should also examine privacy requirements and test performance on real workloads rather than relying solely on vendor benchmarks.
If you need local AI, compact models, or customizable foundation models, Liquid AI is worth exploring. Start with a suitable model, verify its license, and measure its performance before moving into production.
Oliver Wilson is an AI researcher and tech writer living at the intersection of human creativity and machine intelligence. At AixOrbit.com, he decodes complex neural networks, generative AI and emerging tech trends into actionable insights making sure humans stay one step ahead of the algorithms.